Why Enterprise AI Is More of a Governance Problem Than an LLM Problem
Enterprise AI isn't an LLM problem. It's a data governance crisis. Learn how architects solve RBAC, PII, and data residency to deploy secure AI at scale.
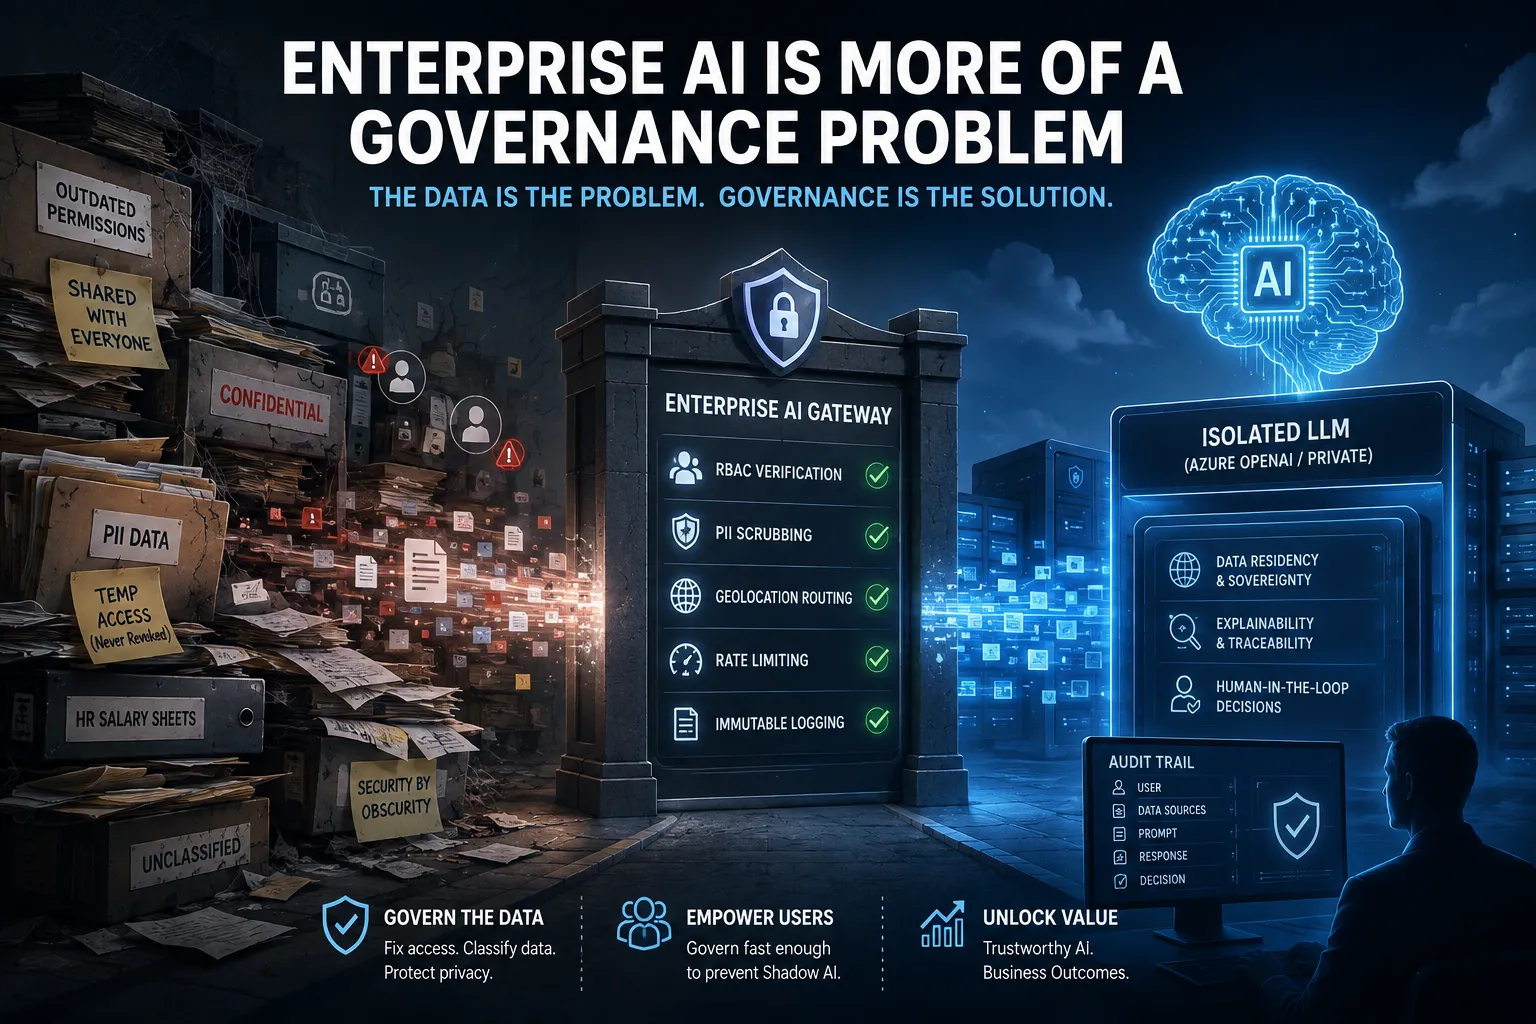
Most Enterprise AI initiatives aren’t stalling because LLMs aren’t smart enough. They are stalling because our internal data is an absolute disaster.
The playbook right now is predictable: leadership wants AI yesterday, security blocks public tools like ChatGPT or Gemini, and IT is told to deploy a tenant-isolated instance inside a walled garden, such as Azure OpenAI, Copilot, or ChatGPT Enterprise. Contracts are signed, endpoints are provisioned, and executive leadership breathes a sigh of relief assuming the hard part is over.
But provisioning an LLM is barely 10% of the journey. The remaining 90% is the unglamorous, high-friction work of controlling what that model touches, where its tokens travel, and how it behaves when exposed to decades of accumulated data debt. Here is why Enterprise AI is fundamentally an identity, privacy, and security project that just happens to use an LLM at the very end:
The Technology is the Easy Part
Let’s get one thing out of the way: the foundational technology is largely “solved” for what we need to do. Current enterprise models are incredibly capable and easily handle the vast majority of standard corporate use cases. Whether you are building complex multi-agent workflows in Azure AI Foundry or setting up a basic RAG pipeline, your enterprise AI harness infrastructure is ready.
You can provision a secure, private endpoint in minutes. But an LLM sitting in an empty cloud tenant is useless. Its actual business value comes entirely from its context, your corporate data. And that is exactly where our legacy architectures start to crack.
The RBAC Crisis: The Ghosts of Permissions Past
When you point an enterprise AI at your internal systems like SharePoint, Jira, or Confluence, it naturally respects the permissions of the user asking the question.
This sounds perfectly logical until you remember how we actually manage data. Most enterprises are sitting on years of terrible, outdated RBACs. Folders get shared broadly for a quick project, permissions are inherited incorrectly, and access is almost never revoked when someone changes departments.
Without an LLM, finding the confidential draft merger plans or an unencrypted HR salary sheet meant digging through thousands of nested folders. We basically relied on security by obscurity. An AI, however, indexes everything instantly. If a sensitive folder was accidentally left “public to the organisation” years ago, the AI will happily summarise it for an intern today. If you want to deploy AI safely, you have to lead a massive cleanup of unstructured data access and enforce true zero-trust policies before you ever fire off that first prompt.
PII Exposure and The Context Window Trap
Beyond just file permissions, we have to look at the shape of the data itself. What happens when a business user asks an AI to summarise a messy, real-time data file of customer support tickets?
All of that data, including PII like names, phone numbers, and account details, gets pulled directly into the AI’s context window for processing. Even if the AI is hosted internally, exposing raw PII attributes, health records, or sensitive financials to an inference engine violates core privacy principles. You simply cannot rely on users to manually redact information before they hit “submit.”
The Architectural Fix
Tokens Have Passports: Navigating Data Residency
For global or regulated enterprises, it matters profoundly where your AI physically thinks. Data residency and sovereignty laws dictate that certain citizen or financial data—similar to the regulated flow of OTP authentication in India —cannot cross geographic borders.
It is a common architectural blind spot to assume that keeping the database local is enough. In the AI world, the inference, the actual processing of the tokens, must also happen within the allowed geographic boundary. You cannot send European or localised APAC customer data to a US-hosted AI model for summarisation without triggering sovereignty violations. We have to design multi-region AI deployments, pinning localised models to specific geographies so that regulated data never leaves its required jurisdiction.
Regulated Realities: Explainability and Traceability
In heavily regulated environments, decisions carry serious weight. If an enterprise AI assists in denying a customer claim, flagging a transaction, or generating code for a production financial system, the business holds the legal liability.
When the auditors come knocking, you cannot point to a server rack and say, “The AI did it.” Regulators require a provable, immutable trail. You need to log exactly who initiated the request, what specific internal data chunks were retrieved via RAG and fed to the AI, and the exact output generated. Furthermore, critical decisions require a “Human-in-the-loop” workflow. The AI acts as an advanced reasoning engine that proposes a decision, which a credentialed human then verifies and commits.
The Enterprise AI Gateway Pattern
To solve this without rewriting every application, modern architecture relies on an AI Gateway, a centralised choke point for all AI traffic.
+-------------------+       +-----------------------+       +-----------------------+
|                   |       |   ENTERPRISE AI       |       |                       |
|  Business Users / | =====>|   GATEWAY LAYER       |=====> |  Isolated LLM         |
|  Internal Apps    |       |                       |       |  (e.g., Azure OpenAI) |
|                   |       | - RBAC Verification   |       |                       |
+-------------------+       | - PII Scrubbing       |       +-----------------------+
                            | - Geolocation Routing |                 |
                            | - Rate Limiting       |                 |
                            | - Immutable Logging   | <---------------+
                            +-----------------------+
FinOps and The “Shadow AI” Threat
Finally, we have to talk about the bill and the culture. Enterprise APIs charge by the token. Without strict rate limiting and centralised FinOps management built into that gateway, a single runaway script looping through an API can rack up a massive cloud bill over a long weekend.
But there is a flip side to this control. If IT locks things down too tightly, or takes six months to approve a basic internal AI tool, you face a much worse problem: Shadow AI. Your employees know these tools make them vastly more productive. If the enterprise governance is too slow, users will simply bypass it. They will copy-paste sensitive corporate code or financial data onto their personal devices to use consumer-grade AI tools, completely bypassing your carefully designed security perimeter.
This leaves architecture teams walking a tightrope: we have to govern the data, but we have to do it fast enough to keep users inside the walled garden.
The Architectural Takeaway
Enterprise AI isn’t an innovation project, it is a mirror. It reflects every shortcut we ever took with access permissions, every unclassified spreadsheet sitting on a SharePoint, and every vague compliance policy we hoped nobody would test.
If you treat Enterprise AI as a software rollout, it will stall in pilot purgatory. But if you treat it as the ultimate forcing function to finally fix your identity, privacy, and data governance, you won’t just deploy a model, you will build the resilient architectural foundation your business actually needs.
Key Takeaways
These key takeaways are synthesized and auto-generated by AI from the article content for quick reference.
Why is AI data governance important?
AI data governance is important because enterprise AI models index and correlate internal documents at scale, instantly exposing legacy permission flaws, unencrypted files, and sensitive customer records. Without strict governance, models can leak confidential data, violate privacy regulations (like GDPR and HIPAA), and create severe compliance liabilities.
What is AI data governance in enterprise systems?
AI data governance is the architectural framework of security policies, identity controls, and operational guardrails that regulate how corporate data is accessed, processed, and retained by AI models. It encompasses Role-Based Access Control (RBAC), PII scrubbing, data residency compliance, audit logging, and human-in-the-loop verification.
Why is enterprise AI considered a data governance problem rather than an LLM problem?
Commercial LLMs are already capable enough for enterprise tasks, but they cannot safely access corporate data without strict governance. The real challenge lies in resolving legacy permissions, enforcing zero-trust access, preventing PII exposure, and complying with data residency laws before feeding internal data into the model.
What is the RBAC crisis in enterprise AI deployments?
The RBAC (Role-Based Access Control) crisis occurs when an enterprise AI indexes internal systems like SharePoint or Google Drive and inherits outdated, over-permissive access rights. Because an LLM can search and correlate files instantly, it inadvertently exposes sensitive documents—such as unencrypted HR files or M&A plans—that were mistakenly left open to all employees.
How does an enterprise AI Gateway protect PII in LLM prompts?
An enterprise AI Gateway acts as an interception layer between users and language models. It automatically detects and masks sensitive Personally Identifiable Information (PII) before the prompt reaches the LLM context window, then securely re-hydrates the data in the final response so actual customer identities are never exposed during inference.
What is the difference between data storage residency and AI inference residency?
Data storage residency ensures internal databases remain within a specific legal jurisdiction, whereas AI inference residency requires that the actual computing and token processing occur within that same geographic boundary. Sending regulated local data to an offshore AI model for processing violates data sovereignty laws like GDPR.
What is the role of an Enterprise AI Gateway pattern?
An Enterprise AI Gateway serves as a centralized architectural control point for all AI traffic. It standardizes model access across the organization by handling prompt validation, RBAC verification, PII redaction, geolocation-based model routing, rate limiting (FinOps), and immutable audit logging.
How does enterprise AI governance prevent Shadow AI?
If enterprise approval processes are overly restrictive or slow, employees inevitably copy-paste sensitive corporate data into unmonitored consumer AI tools. Effective governance provides secure, approved enterprise AI environments fast enough to satisfy employee productivity demands while keeping corporate data inside the organizational perimeter.
Why is traceability required for enterprise generative AI in regulated industries?
Regulated organizations are legally liable for decisions influenced by AI. Traceability requires maintaining an immutable audit trail of the user's identity, the specific context chunks retrieved via RAG, the system prompts applied, and the raw model outputs to prove compliance and support human-in-the-loop validation during audits.